Technology Partner iWave

Xelera and iWave:
Ultra-low latency AI inference for HFT on iWave XFibre SmartNICs

Deploy Gradient-Boosted Trees and neural networks on iWave G30, G35 and G63 PCIe Accelerator Cards, and Neural Networks on the Versal™-based G63. Two deployment modes, one trained model file, one API.

~250 ns

Silva inline GBT inference, p99
(reference benchmark, LightGBM)*

~ 350 ns

iWave tick-to-trade framework,
end to end, excluding trading logic

1 API

C, C++, C# and Python,
identical across both modes

Silva, now on iWave hardware

iWave XFibre SmartNICs combine 10G to 400G Ethernet with AMD adaptive SoCsand the iWave HFT framework: a full hardware tick-to-trade pipeline.

Xelera Silva adds the decision layer. Train in XGBoost, LightGBM, CatBoost or PyTorch, then run the model as a turnkey accelerator, or as a Silva IP core inside the iWave HFT framework. Switching modes is a configuration change, not a rewrite.

Supported cards

10/40 GbE
G30-XFibre
- 10/40G®
Zynq™ UltraScale+™ SmartNIC
  • FPGA: AMD Zynq™ UltraScale
    +™ZU7CG MPSoC

  • Network: 4× 10GbE SFP+ (1× / 4×config)

  • Host: PCIe Gen3 x8, FHHL

  • AI Models: Gradient-Boosted Trees

  • Best for: Single-venue 10G feedhandlers, compact treeensembles

100 GbE
G35-XFibre-
100G®
Zynq™ UltraScale+™ SmartNIC
  • FPGA: AMD Zynq™ UltraScale
    +™ZU11/ZU19EG MPSoC

  • Network: 2× 100GbE, NVMe expansion

  • Host: PCIe Gen3 x16, FH3/4L

  • AI Models: Gradient-Boosted Trees

  • Best for: Multi-feed 100G, larger treeensembles, concurrentstrategies

400 GbE
G63-XFibre-
400G®
Versal™ Premium SmartNIC
  • FPGA: AMD Versal™ Premium
    (VP1102 to VP1552 family)

  • Network: 400G, 112G PAM4 transceivers

  • Host: PCIe Gen5 x8, FH3/4L

  • AI Models: Gradient-Boosted Trees andNeural Networks

  • Best for: 400G aggregation, LSTM andattention models, large multistrategy books

Deployment modes

Two ways to run Silva on XFibre

From fully turnkey to fully in-hardware: choose how much of the stack Xelera delivers and how much comes from iWave. The trained model file is identical in both.

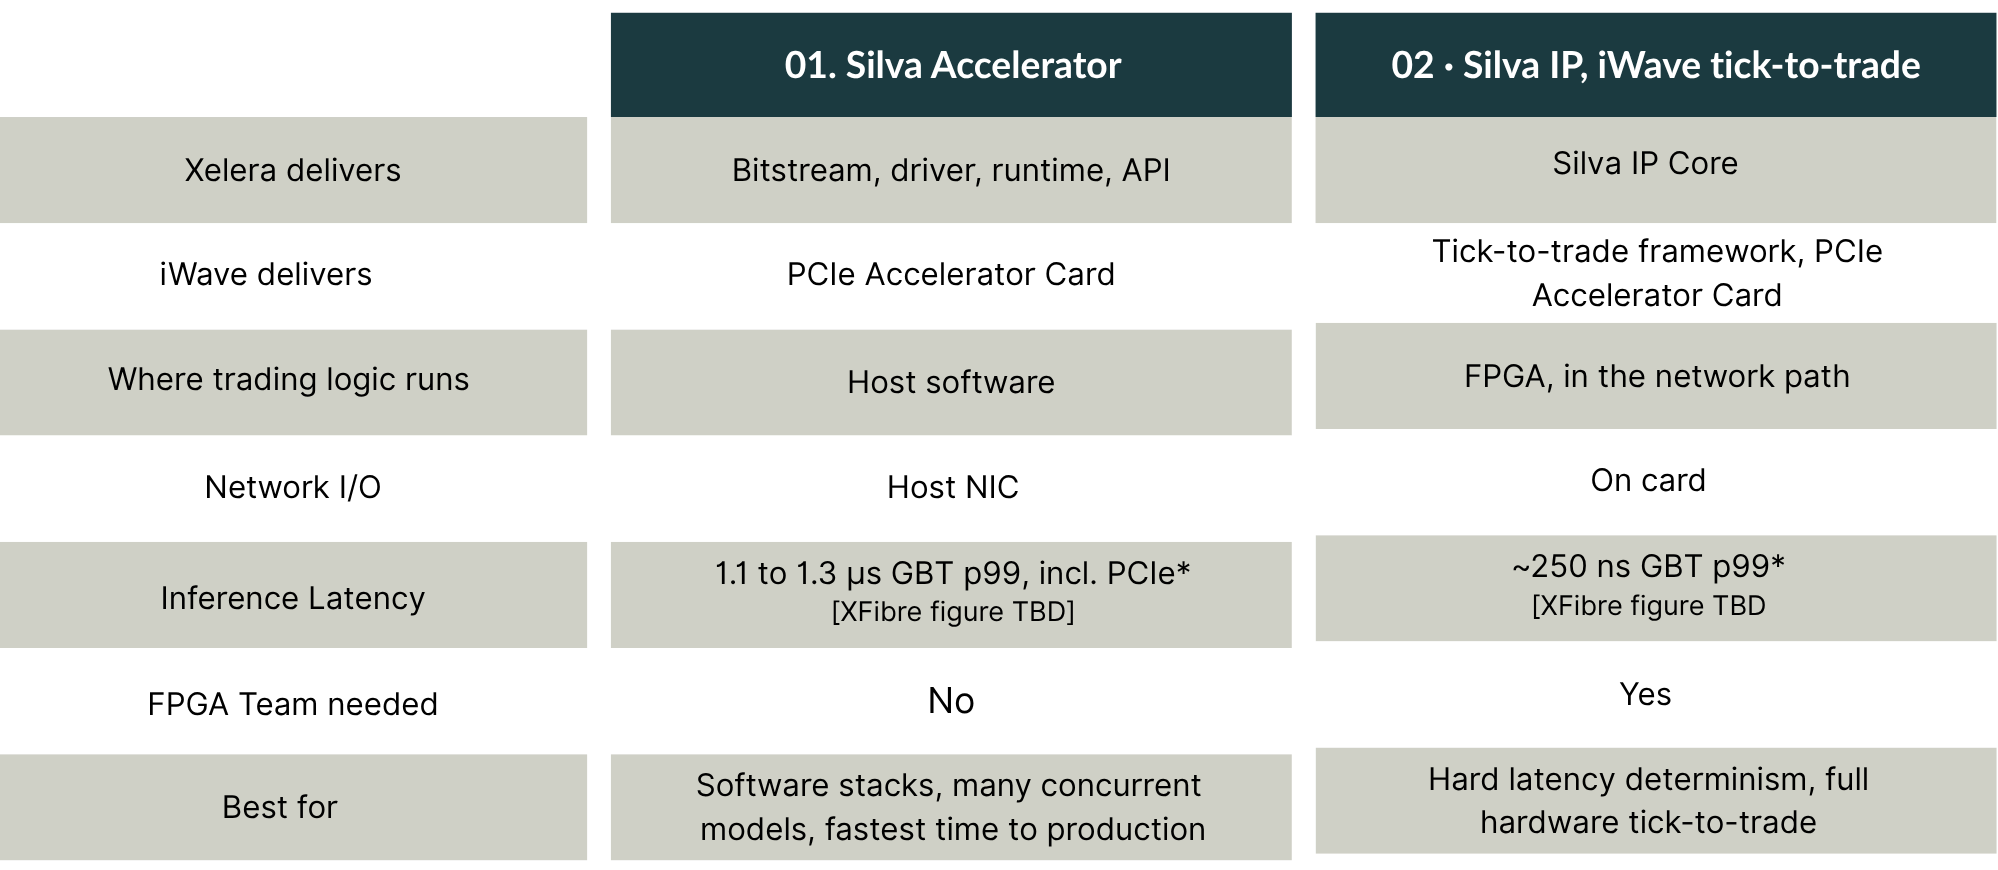
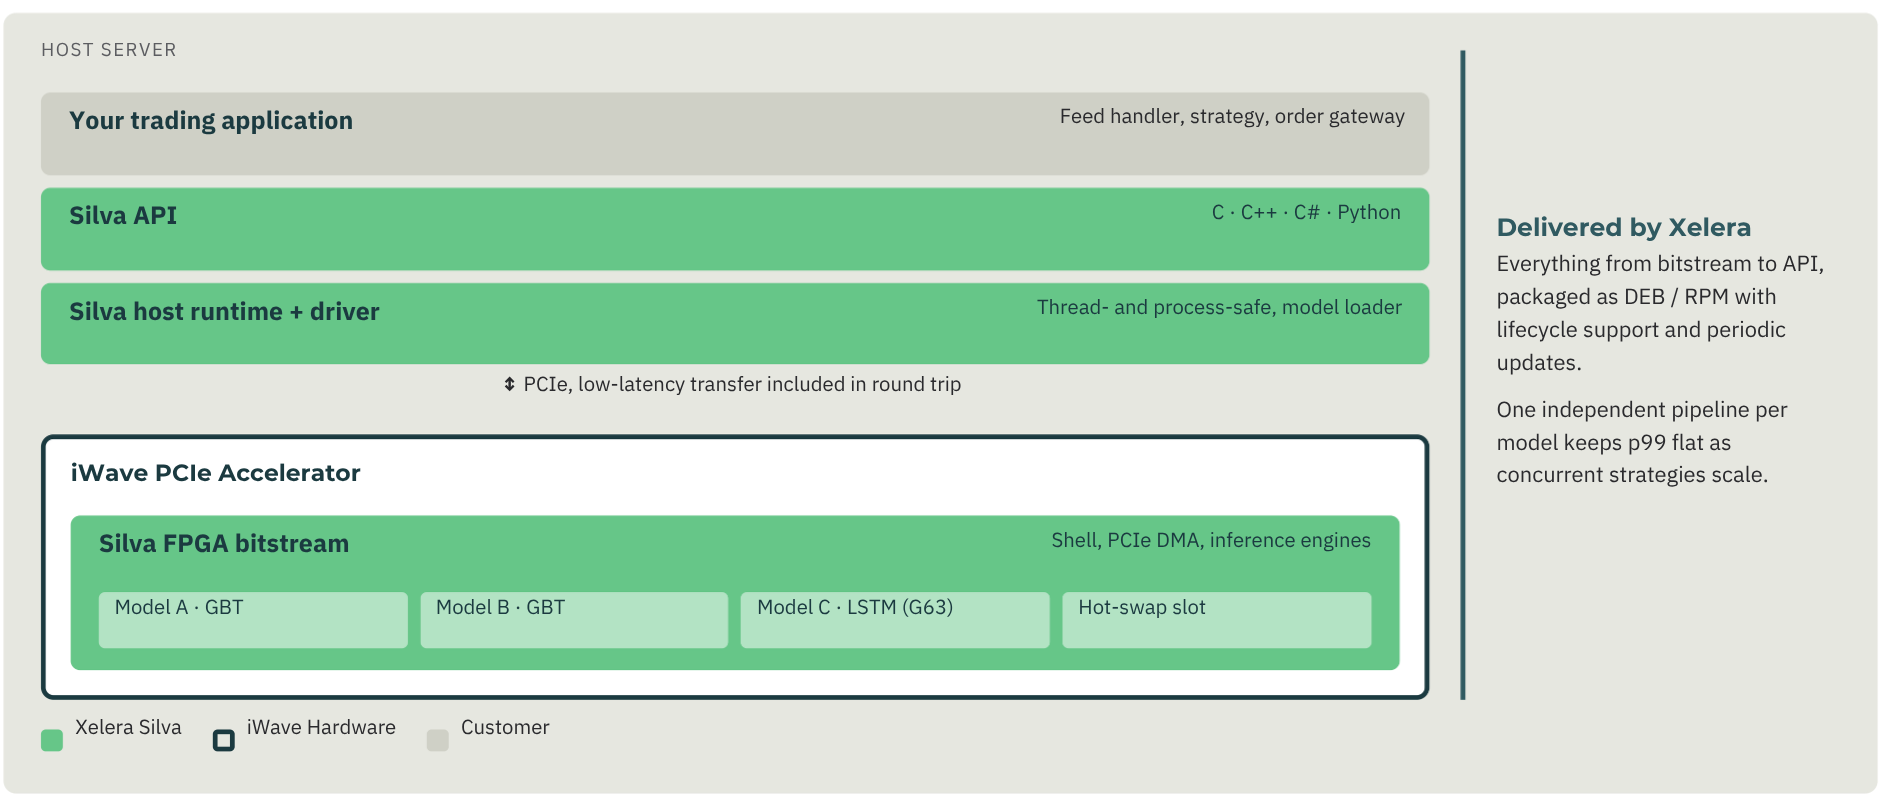
Silva Accelerator: turnkey offload

The Silva IP core replaces the AI inference stage of iWave's inline tick-to-trade framework. Market data isdecoded, scored and turned into an order without leaving the chip. iWave provides the framework and the PCIeAccelerator Card.

Data path: Host to card over PCIe
Xelera delivers: Bitstream, driver,runtime, API
iWave delivers:  PCIe Accelerator Card
‍

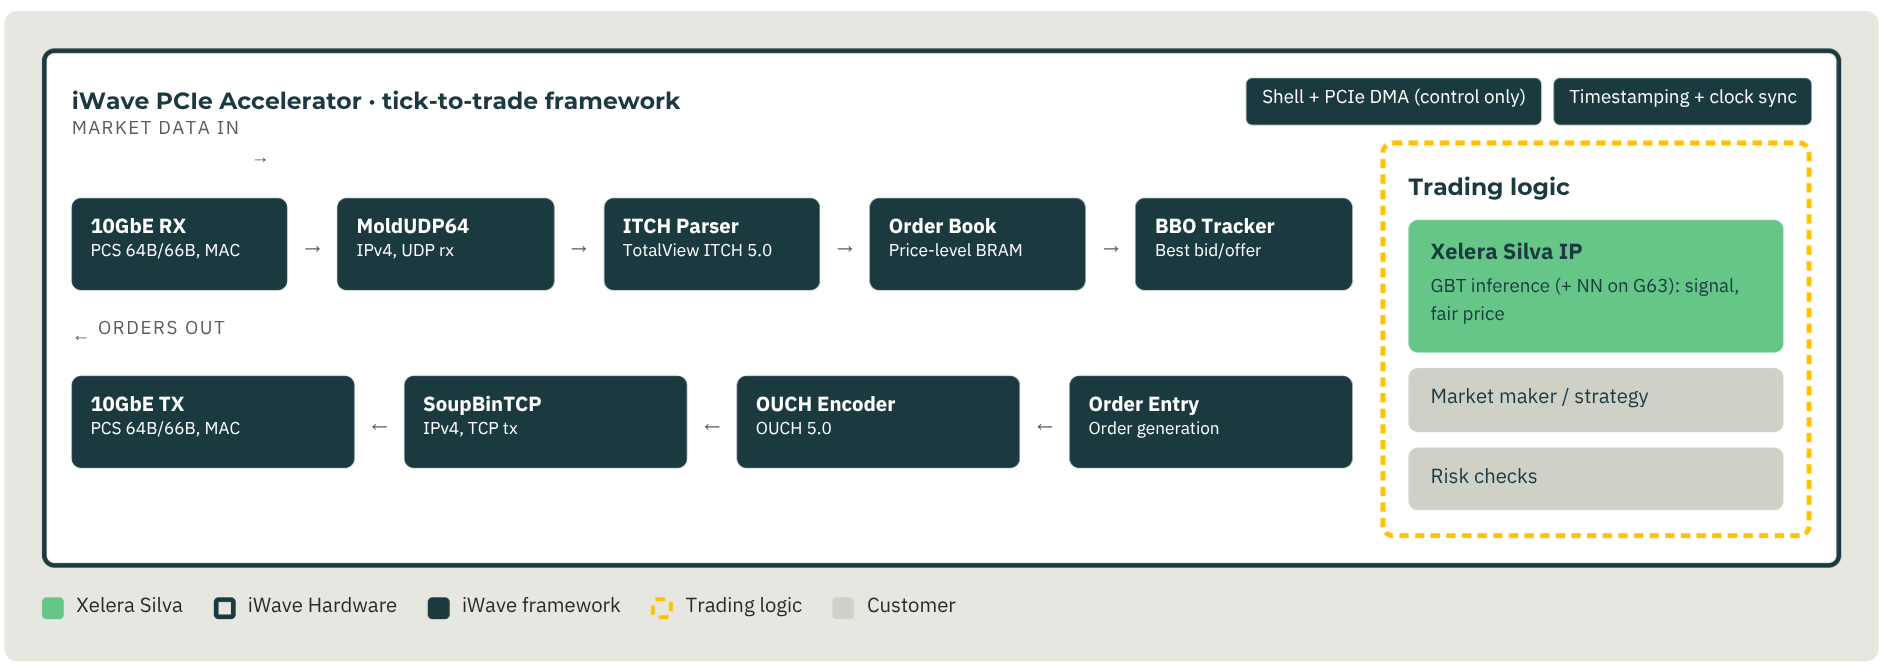
Silva IP in the iWave tick-to-trade framework

The Silva IP core replaces the AI inference stage of iWave's inline tick-to-trade framework. Market data is decoded, scored and turned into an order without leaving the chip. iWave provides the framework and the PCIeAccelerator Card.

Data path: on-chip, No PCIe
Xelera delivers: Silva IP Core + model compiler
iWave delivers:  Tick-to-tradeframework, PCIeAccelerator Card
‍

Modes at a glance

Bring your own model.

Train with standard frameworks on your data. Deploy the same model file in any mode, hot-swap without stopping the card.

Gradient Boosted Trees
XGBoost, LightGBM, CatBoost. Numerical float32
and categorical features
G30 - G35- G63
Neural Networks
LSTM, MLP, Conv1D, single-head attention in float16 / bfloat16. State preserved across calls.
G30 - G35 - G63

Getting Started

Features Icon

Evaluate on CPU

Run your model in Silva CPU-only mode on any Linux box. Zero hardware leadtime.

Features Icon

Pick card and mode

Match bandwidth (10G, 100G, 400G),model class and integration depth with Xelera engineers.

Features Icon

Integrate

Install the turnkey bitstream and API, or drop the Silva IP into the iWave HFT framework with the example design.

Features Icon

Go live

Lifecycle support, periodic updates and model hot-swap in production.

News

Learn more about currents trends in acceleration tech